Lecture 3 - Genetics of Obesity Part 1
 Call Kai
 Learn
 Practice Test
 Spaced Repetition
 Match
 Flashcards
 Knowt Play
1/42

There's no tags or description
Looks like no tags are added yet.
Name | Mastery | Learn | Test | Matching | Spaced | Call with Kai | Chat |
|---|
No analytics yet
Send a link to your students to track their progress
43 Terms
What is a genome?
1. The genetic material of an organism → chromosomes of eukaryotes & prokaryotes, DNA/RNA of viruses
2. The genome contains an organism’s hereditary information
3. The genome consists of both coding and non-coding information
How many genomes have been sequenced to date?
180+

What is the C-value paradox?
organismal complexity not correlated with genome size
Why do we sequence genomes?
accelerate biomedical research -> identify variants related to disease
create global views that requrie a concerted effeort
improvements in medicine -> discover therapeutic targets but also has to be evaluated with clinical factors
DNA forensics -> Human identification.
Better understadning of evolution and human mifgration
More accurate risk assessment
Develop new informatics tools for massive amounts of data
Characterizing the genome
Gene Networks (systems biology)Gene Networks (systems biology)
What is the generation study?
The Generation Study is evaluating whether whole-genome sequencing can identify more than 200 rare, treatable genetic conditions shortly after birth, potentially enabling earlier diagnosis and care
The goal is to determine whether the information can be used for early identification and treatment before the disease.
What are ways that genome base knowledge is being used for health benefits?
Use genomic information for personalized (precision) medicine → “PPPP”: prediction, prevention, personalization, and participation
Determine how genes contribute to health and disease, as well as responses to lifestyle (drugs, foods, exercise, etc
Identify predictors of disease susceptibility and drug response for the early detection of complications and adverse side-effects
Acquire a new understanding of genes and pathways, leading to potential new therapeutic strategies
Advancing technology in healthcare (e.g., new diagnostic kits)
Motivate behavioral changes → empowering individuals through personalized information about themselves
What is precision medicine?
Personalization → unique treatments for each individual
Precision → classifying people into well characterized subgroups to develop therapies
How were genomes studied in early days?
Sanger method for sequencing
What is the Sanger method for sequencing?
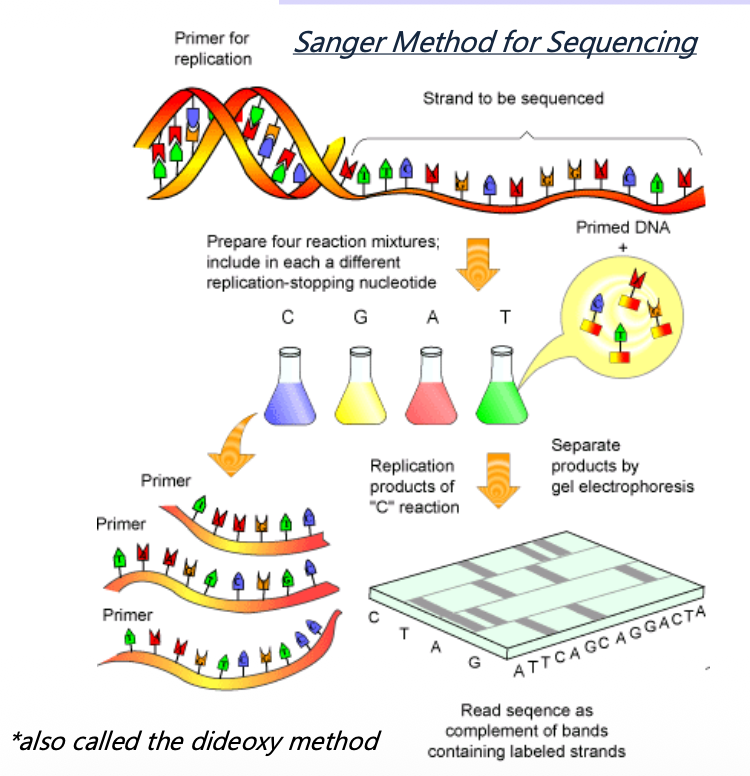
Start with the DNA stadn you want to sequence -> you then add a primer which tells the DNA polymerase where to start copying
There are two types of nucleotides. dNTPs= normal nucleotides that let the stradn keep growing. ddNTPS= Stop the DNA stand from going because it lacks the 3'-OH group, the DNA synthesis will stop Because you have some ddNTPs mixed in, sometimes the polymerase accidentally incorporates one of these STOP nucleotides. So you end up with DNA fragments of different lengths. You get different legnths because the STOP nucleotide can get incorporated at different points in different copies of the DNA.
You have 4 reactions each with a differet ddNTP so that you know which base it stopped at.
What is the importance of the structure of DNA?

The DNA polymerase cannot add any more nucleotides if ther his no OH group of the ddNTP
How do we read the Sanger gel?

Then, putting them in a gel with 4 lanes seperates them by size which then allows you to read which base came first because on the size and which lane it is in.
What is chromatogram?
Same principle but in automated form. Each of the coloured peaks represents a base and the software performs analysis to indicate whether there is confidence in the gel. Clean and separated peaks indicate confidence and overlapping or weak peaks make it less certain.
DNA copying → random fluorescent ddNTP stops → fragments of different lengths → separate by size → read colours → DNA sequence
What is the public consortium?
(Human Genome Project)
• Interested in the entire genome (introns and exons)
• Sequence all 3 billion base pairs using bacterial artificial clones (BACs) → chromosomes are cut up into big pieces and organized before sequencing
Break genome into large pieces → BACs (containers holding large DNA fragments)
Map BACs → determine where each BAC belongs in the genome
Sequence each BAC
Assemble sequences in the known order
KEY IDEA:
Large BAC pieces → map location → sequence → assemble
What is the private consortium?
(Celera Genomics)
• Interested in protein-coding regions of the genome
• Generate a whole-genome draft using shotgun sequencing →
Randomly fragment the genome → thousands/millions of small pieces
Sequence all the pieces
Computer finds overlapping sequences
Use overlaps to assemble the pieces into the complete genome
KEY IDEA:
Randomly break → sequence → find overlaps → computer assembles
Primary differences between consortiums:
• How DNA was fragmented
• How fragmented DNA was assembled
What was the limitation with the Sanger method?
The challenge was how to sequence the entire genome by Sanger, which works for ~1500 bps → they have to make the DNA smaller to use the Sanger method
BACs vs plasmids
Both are circular DNA vectors that replicate
in bacteria
• Standard plasmid vectors carry small DNA
inserts; BACs can hold 150kb fragments of
DNA
How was the DNA fragmented in each method?
Step 1 – Fragmenting DNA: Both methods start by cutting the genome into pieces, just at different scales. BAC-to-BAC cuts into large ~150,000 bp chunks using restriction enzymes. Shotgun sequencing cuts
into much smaller pieces (2,000 bp and 10,000 bp) by physically shearing the DNA (forcing it through a fine syringe).
How were fragments amplified in each method?
Step 2 – Amplifying Fragments: You can't sequence a single DNA molecule directly — you need many copies. So each fragment is inserted into a circular DNA vector (BAC or plasmid) that bacteria will
replicate for you. The purple box explains the difference: BACs can carry huge inserts (150kb), while standard plasmids only hold small inserts. This is why BAC-to-BAC uses BACs for its big fragments, while
shotgun sequencing uses ordinary plasmids for its small fragments.
Why must DNA fragments be amplified before sequencing?
You need many copies of each DNA fragment for sequencing.
→ Insert fragment into a vector → bacteria replicate it → many copies
Why do BAC-to-BAC sequencing need to map the BACs before sequencing?
Step 3 (aligning BACS) → Because BACs are large (~150 kb), you first need to determine where they belong on the chromosome and how they overlap.
KEY IDEA:
Map first → sequence later
Since BAC-to-BAC used huge 150kb fragments, before sequencing them you first need to figure out where each BAC fragment falls along the chromosome and how they overlap with each other — using "sequence landmarks" like postal codes to map ~30,000 BACs into order. Shotgun sequencing skips this step entirely, because it sequences everything first and uses computational overlap-matching afterward instead of physical mapping beforehand.
What is BAC fingerprinting and what does it tell you?
Cut each BAC with a restriction enzyme (e.g., HinfI) → compare the resulting fragment-size patterns.
If two BACs have similar fingerprints → they overlap.
KEY ID:
Fingerprinting = relative order/overlap
What does STS/landmark mapping tell you?
Tests BACs for known short DNA markers whose chromosome location is already known.
→ Tells you where the BAC is located on the chromosome.
KEY ID:
STS = absolute chromosome position
What is the difference between fingerprinting and STS mapping?
Fingerprinting → relative order
"BAC 1 overlaps BAC 2, which overlaps BAC 3."
STS/landmarks → chromosome location
"This BAC is on chromosome 3."
KEY IDEA:
Fingerprinting = connect the pieces
STS = anchor them to the chromosome
Why does BAC-to-BAC require TWO rounds of DNA fragmentation?
Step 4 - Fragmenting BACS → The 150-kb BAC is still too large for Sanger sequencing, so it must be broken down again.
KEY IDEA:
Genome → BAC → small sequencing fragments
Why is assembling BAC-to-BAC sequences easier?
You already know which ~150-kb region you're sequencing.
→ You're only assembling fragments from one small, known region
→ Less chance of confusing repetitive sequences from different parts of the genome.
KEY IDEA:
BAC-to-BAC = you already know the neighborhood
How is sanger sequencing different in each method?
BAC-to-BAC you only sequence from one side and with shotgun sequencing you have to sequence form both sides
What is the major challenge with whole-genome shotgun sequencing?
Repetitive DNA.
Because the genome contains repeated sequences, two fragments from different locations can look identical or appear to overlap.
→ Computer may incorrectly assemble them.
If only the ends of shotgun fragments are sequenced, how does the entire genome get covered?
The genome is randomly fragmented into millions of overlapping pieces.
A region missed by one fragment is likely covered by another fragment that starts at a different location.
→ With enough coverage (e.g., 5–10×), essentially every base is sequenced by at least one fragment.
KEY IDEA:
Random fragments + lots of coverage = whole genome gets covered
Why does shotgun sequencing benefit from sequencing both ends of a DNA fragment, while BAC-to-BAC doesn't need as much information from both ends?
The difference is how much is already known about the fragment's location.
BAC-to-BAC: BACs are mapped first, so you already know roughly where the DNA came from → less information is needed to assemble it.
Shotgun: fragments are random and unmapped, so reads from both ends provide extra information about the fragment's location + orientation, helping assembly.
KEY ID:
BAC-to-BAC = map first → less ambiguity
Shotgun = no map → both-end information helps
When was the whole human genome published?
Launched in 1990, completed in 2003.
BAC advantages?
BAC approach — Advantages
1. "Reduced chance to misassemble because location is better known" — This is exactly the point from our contig discussion. Because BAC-to-BAC does all that mapping/fingerprinting work upfront (Step
3), you already know where each BAC belongs on the chromosome before you sequence it. So when you're assembling reads into a contig, you're only ever trying to fit pieces within one known, small 150kb
region — there's very little risk of the computer mistakenly gluing together sequence from two completely different parts of the genome, because you already know which neighborhood you're working in.
2. "Sequencing step is quick, don't need to sequence both ends of DNA" — This is the direct payoff of the "one end is enough" conversation we just had. Since BAC fragments (after Step 4) are shattered
small enough that one Sanger read covers the whole fragment, you don't need the paired-end trick shotgun relies on — you just read straight through in one pass.
BAC disadvantages?
BAC approach — Disadvantages
1. "Experimentally laborious and time consuming" — Think about everything BAC-to-BAC required in the wet lab: isolating ~30,000 BACs, fingerprinting each one with restriction digests, running gels,
testing for STS markers by PCR, ordering everything into a tiling path — before you even get to sequence anything. That's a massive amount of physical benchwork.
2. "Bioinformatically heavy" — Even thouH
Shot gun advantages?
Shotgun approach — Advantages
1. "Overall process is experimentally quicker" — This is the flip side of BAC's big disadvantage. Shotgun skips the entire BAC-mapping stage (Steps 2-3 in the BAC pathway) entirely — you just shear the
whole genome randomly and start sequencing immediately. Much less lab work upfront.
Shotgun disadvantages
Shotgun approach — Disadvantages
1. "Bioinformatically heavy" — This is the trade-off for skipping the lab work — the computational burden shifts almost entirely onto the assembly step. Since you have no prior map, a computer has to
reconstruct the entire genome from scratch using only overlap-matching and paired-end distance clues across millions of random fragments — a vastly bigger computational puzzle than BAC-to-BAC's
contained, per-BAC assembly.
2. "Major problems dealing with repeat sequences in DNA" — This is exactly the repeat-sequence issue from our earlier conversation. Because shotgun has no prior map telling you which region a
fragment came from, identical repeated sequences scattered across different parts of the genome can be indistinguishable to the assembly software, causing incorrect merges. Paired-end reads (the
2,000/10,000bp trick) help resolve some of this, but it remains a fundamental weakness of the approach — you're never fully protected from repeats the way BAC-to-BAC is, since BAC-to-BAC already
isolated each stretch of genome into its own known location before assembly even starts.
What was the major gain from the T2T-CHM13 human genome assembly compared with GRCh38?
It provided access to previously unresolved repetitive and structurally complex DNA regions.
KEY IDEA:
T2T-CHM13 → fills in previously missing/unclear genome regions
What major types of genomic regions were missing/unresolved in GRCh38?
Centromeric regions → highly repetitive central regions of chromosomes
Segmental duplications → large, highly similar DNA sequences found at multiple locations
What are segmental duplications?
Large DNA segments with highly similar copies at multiple locations in the genome.
KEY ID:
Segmental duplication = large, nearly identical DNA copies in different genomic locations
Why do segmental duplications make genome assembly difficult?
Their copies are very similar/near-identical, so sequencing reads from different genomic locations can look like they belong together.
→ Assembly software can incorrectly join sequences from different locations.
KEY IDEA:
Similar copies in different places → difficult to tell where reads belong
Why are segmental duplications biologically important?
Because their highly similar copies can cause misalignment during recombination, which can lead to:
→ Deletions
→ Duplications
→ Other rearrangements
Why does this matter if the human genome is 99.9% identical?
his still means that 2.9
million base pairs can differ
What is the active research with precision nutrition?
the study aims to study why individuals repsond differently to food by combining genomic information with diet, metabilic, physiolocal, micobiome, behaviourla, and environemtnal data.
They hope to develop algothricms that predict how people will repsond to foods,
Innate talent vs training?
198 twin pairs, 72 were monozygotic
• Genetic factors explained between 52% (standing
long jump) to 79% (sit and reach) of the individual
variation in motor performance.
• Individual-specific environmental factors explained
the remaining variation.