econometrics
 Call Kai
 Learn
 Practice Test
 Spaced Repetition
 Match
 Flashcards
 Knowt Play
1/17

There's no tags or description
Looks like no tags are added yet.
18 Terms
OLS
ordinary least squares — chooses coefficients that limit minimized sum of squared residuals to find the best-fitting linear regression line.
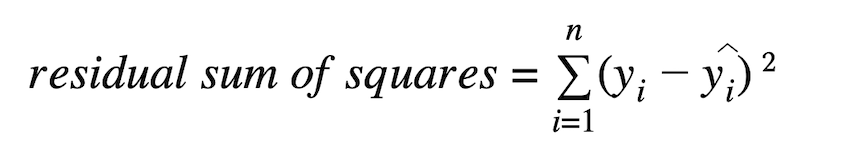
exogeneity
explanatory variables carry no information about the error
endogeneity
an explanatory variable is correlated with error; this biases OLS
omitted variable bias (OVB)
bias caused by leaving out a variable that affects Y and is correlated with an included regressor
OVB = β * [cov (x,z)] / [var(x)]
classical linear regression model (CLRM)
linearity in parameters — β’s are not exponents
random sampling
no perfect multicollinearity
zero conditional mean: E ( e | x ) = 0 — exogenous
homoskedasticity: var (e|x) = variance
normality of the errors
gauss-markov theorem
if CLRM assumptions hold, OLS = BLUE
best — small variance
linear
unbiased
estimators
NOT BLUE IF HETEROSKEDASTIC
confidence interval
range of plausible values for β for a particular significance level
p-value
probability of getting t-stat if null hypothesis is true
R²
proportion of sample variation in Y explained by the regression
R² = 1 - RSS/TSS = ESS/TSS
R² adjusted
penalizes the addition of superfluous regressors
R² adjusted = 1 - (RSS/(n-k-1))/(TSS/(n-1))
average marginal effect (AME)
calculated the marginal effect for each observation, then takes the average
partial effect at the average (PEA)
calculates the marginal effect with explanatory variables set to their sample averages
missing completely at random (MCAR)
a value is missing either related or unrelated to any observed or unobserved data values
solutions:
ignore
missing indicator method → create a dummy for missingness
OLS still has all desirable properties
serial correlation (autocorrelation)
errors from different observations over time are correlated
solution: use durbin-watson test
strict exogeneity
today’s error has mean 0 given explanatory values from all time periods — past, present, & future
contemporaneous exogeneity
today’s error has mean zero given today’s explanatory variables — might still be realted to past or future explanatory variables
attenuation bias (NOT VOCAB WORD)
in simple regression, biases the slope → 0
white test/park test
tests detect heteroskedasticity—unequal error variance.
small p-value: Evidence of heteroskedasticity.
large p-value: Insufficient evidence; does not prove constant variance.
use robust standard errors to account for heteroskedasticity.