Module IV: Dimensionality Reduction and Clustering (not on midterm)
 Call Kai
 Learn
 Practice Test
 Spaced Repetition
 Match
 Flashcards
 Knowt Play
1/7

Earn XP
Description and Tags
* review the slides for this unit!!
8 Terms
k-means clustering
principal component analysis (PCA)
"best" as projection into top k principal components (PCs) as directions of highest variance in data
The PCA coordinate frame is defined such that: PC1 is the direction of highest variance in the data PC2 is the direction of next highest variance orthogonal to PC1 PC3 is the direction of next highest variance orthogonal to PC1, PC2 PC4 is the direction of next highest variance orthogonal to PC1, PC2, PC3
no labels
So here is the final result of PCA. It has given us a means to take our 2D data in (X1,X2) and represent it in 1D (PC1) while maintining a large fraction of the information content (i.e., variance).
This is the sense in which dimensionality reduction "works": if you can approximate a data set in a lower dimension, we can have an easier time visualizing it, storing it, transmitting it, understanding it, or fitting complicated models to the data.
dimensionality reduction
trying to focus in on what is useful
a method for representing data using a lower number of features while still retaining the meaningful structure and properties of the data.

mean vector
variance
will be asked to find variance of a vector
mean-zero
optimization
maximizes variance in PCs
can be done by gradient descent but eigenvalue decomposition or singular value decomposition are better
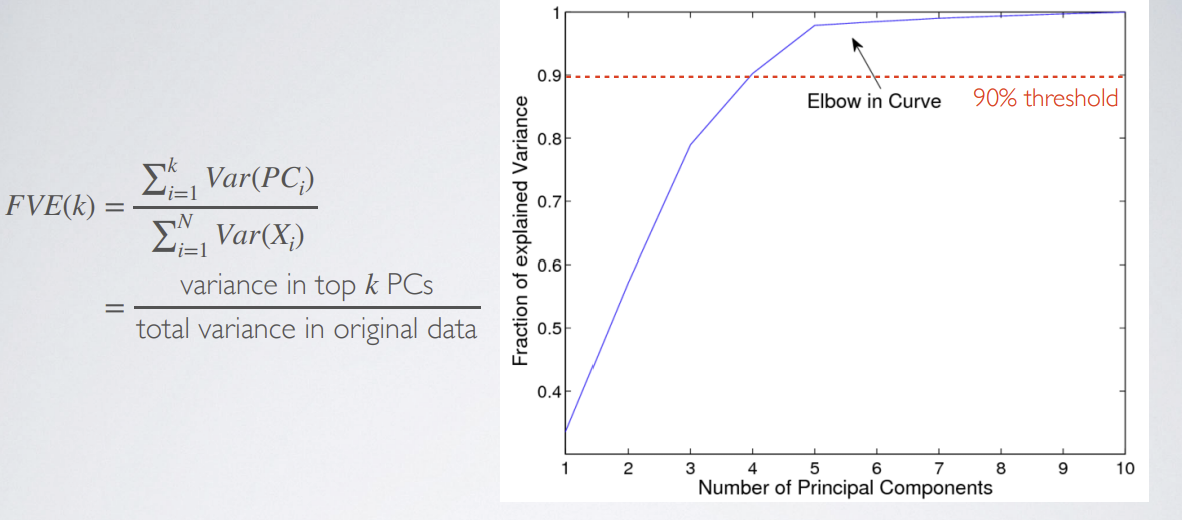
how to choose k
compute fraction of variance explained
use elbow or knee in curve OR where the FVE curve breaks a defined threshold such as 90%/ 95%/99%