the model based perspective
 Call Kai
 Learn
 Practice Test
 Spaced Repetition
 Match
 Flashcards
 Knowt Play
1/19

There's no tags or description
Looks like no tags are added yet.
Name | Mastery | Learn | Test | Matching | Spaced | Call with Kai | Chat |
|---|
No analytics yet
Send a link to your students to track their progress
20 Terms
model
simplified representation of a complex object
statistical model
a simplified representation of a data generating process (DGP)
data = model + error
the model is the way to represent predictable part of data, the goal is to minimize error (max predictability of data via model)
loss function
how much information is lost between model and data
three common uses of statistical models
describe
predict
decide
describe
statistical models can help us understand data by summarizing variables or mapping relationships between different variables
predict
a statistical model can help us anticipate how we expect new observations, which were not in our original sample that we used to estimate the model, to look
decide
a statistical model can guide how we choose to behave by helping us understand the likelihood of different consequences of our choices
squared error
most common loss function
minimized by the mean
might try to minimize the sum of squared errors: SSE = Σ(x-x̄)2
mean squared error (MSE)
insensitive to sample size (SSE is sensitive to sample size, as N grows, the SSE does too)
another term for variance (both N and N-1 are just constants used to scale for sample size)
root mean squared error- like SD (original units)
absolute error
less senstive to extreme values, lacks some desirable statistical properties
minimized by median
modeling separate means
score = β0 + β1Cond + Єi
β0 is the mean of the control group
β1 is the difference in means between control and experimental group
Cond is group assignment (0 = control, 1 = experimental)
Єi = residual error
general linear model
yi = β0 + Σβpxip + Єi
Σβpxip for all (P) predictor variables in the model
β0 = intercept, βp is/are slope(s)
parameters are β0 …. βp AND σ2Є (variance of the residuals)
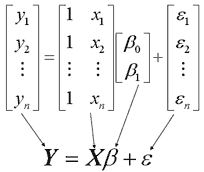
linear algebra form
y = Xβ + Є
y is a vector of length N representing the outcome variable
X is an N x P + 1 matrix of predictors (first column is a column of ones for the intercept (control))
β is a vector of length P + 1 of coefficients, including the intercept
Є is a vector of length N of residuals
overfit
any time you add a predictor to a linear model you estimate with a sample of data, you will reduce error in the predictions within the same sample
bias in which a model captures random variation and treats it as informative signal
but we want to know how the model will generalize/fit to new data

cross-validation
allows us to test how well the model generalizes but it reduces our sample size so we can hold out some data for validation
cross-validation procedure
specify a training dataset
specify a testing dataset
estimate model on training data
make predictions about testing data using model estimated on training data
calculate MSE/RMSE
select model with lowest MSE/RMSE
k-fold cross validation
split the data into k different folds or subsets of equal size
for each fold, train the model on the remaining k-1 folds, then test it on the held out kth fold
repeat
calculate average RMSE
leave one out (LOO) cross validation
for each of the N datapoints, train the model on the remaining N-1 datapoints
make prediction about the single held out data point
calculate average RMSE for each held out datapoint
can be very slow
inference vs behavior
Fisher: we build statistical models to test theories about the world, meant for learning/describing, inference
Neyman: we do inference to decide how to behave, inductive behavior: based on what we’ve learned from data, should I behave a certain way? interventions?
statistical decision theory
subfield of statistics focused on how to make choices based on what we learn from statistical model
interdisciplinary