Problem Set 1 Review
 Call Kai
 Learn
 Practice Test
 Spaced Repetition
 Match
 Flashcards
 Knowt Play
1/14

There's no tags or description
Looks like no tags are added yet.
Name | Mastery | Learn | Test | Matching | Spaced | Call with Kai | Chat |
|---|
No analytics yet
Send a link to your students to track their progress
15 Terms
prediction
Is y-hat close to y?
f-hat may be a black box
inference
How does Y change with X-sub-p?
f-hat must be interpretable
reducible error
How far our estimate f-hat sits from the truth f
A better method, better predictors, or more data can shrink this to 0

irreducible error
No method, however good, gets past this floor
the test MSE will always stay above it

parametric method
assume a form for f, estimate a fixed number of parameters (usually small)
wrong if the form is wrong → overfitting

non-parametric method
no assumed form, estimates f directly by looking for a function that fits the observed data
flexible, and needs far more data (large number of observations)
regression
Y is quantitative
Ex: wage, price, blood pressure
classification
Y is qualitative
Ex: readmitted or not, labeling handwritten numbers (0-9), which customers will convert
training MSE
computed on the observations used to fit the model
_____ decreases as flexibility increases
usually smaller b/c most methods choose their parameters to minimize it
if the curve touches every training point, the ____ is 0
silver line

test MSE
computed on observations the model has never seen
u-shaped because of over/underfitting
red line

degrees of freedom
a single number summarizing how flexible a fitted curve is
a smoother, more restricted curve has fewer _____ than a wiggly one
mean squared error
a metric that is used to measure how well a model’s predictions match the actual values
calculates the average of the squared differences between predicted and actual values
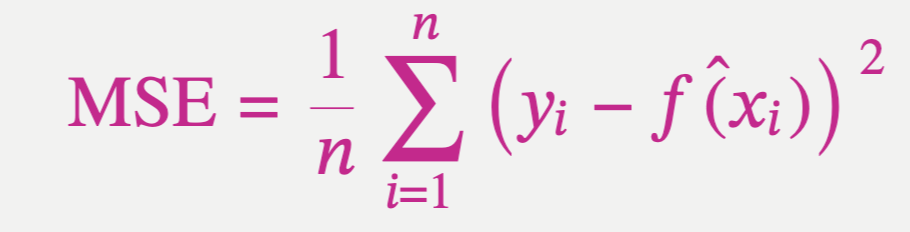
overfitting
following the noise too closely
low train MSE, high test MSE
left of the minimum, the model is too rigid to capture f
right of the minimum, the model is fitting the residual
the dashed floor is Var(residual)
a less flexible model would have had smaller test MSE
train/test split
[ test_size = 0.5 ] → holds out half of the 200 observations for testing
[ random_state = 363 ] → fixes the shuffle so that the split is identical every time the code renders

validation set approach
split the data into training and testing
however, a different split can give a different answer
fit on the training set
evaluate on the test set
keep the model with the smallest test error