Decision Trees
 Call Kai
 Learn
 Practice Test
 Spaced Repetition
 Match
 Flashcards
 Knowt Play
1/15

There's no tags or description
Looks like no tags are added yet.
Name | Mastery | Learn | Test | Matching | Spaced | Call with Kai | Chat |
|---|
No analytics yet
Send a link to your students to track their progress
16 Terms
Classification
Classes(categories) are pre-defined
Supervised model
Data must be labeled
Labeled data → training set
Examples of Classification
Identify individuals with credit risks
Classify responders to a marketing campaign
Classify financial transactions
Classify patients based on symptoms
Pattern recognition
Speech recognition
Letter recognition
View letters as constructed from 5 components
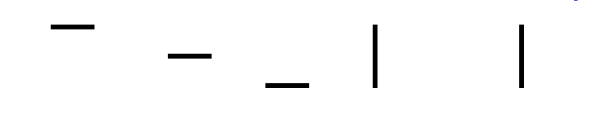
Supervised Learning Model
1) Train the model using “labeled” data
Training data → Model → Classes (Groups)
2) Employ the model to classify (label) new data
New instances of data → model → classes(groups)
Classification Techniques
Decision tree
Distance-based (K nearest neighbor)
Rule-based
Statistical, Logistic regression, Naive Bayesian
Neural Networks
Decision Tree
Classes are predefined
A,B,C,D,F
Decision trees CAN give rules but neural networks DO NOT
Decision trees are explainable models

Decision or Classification Tree
Each internal node is labeled with attribute, Ai
Each arc is labeled with predicate which can be applied to attribute at parent
Each leaf node is labeled with a class, Cj
Examples of Decision Tree
Attributes
Outlook→ Categorical
Humidity → Continuous
Windy → Categorical
Target Variable
Play → What the model is based on

Structure of a Decision Tree
Root - Attribute
Child - Attribute
Leaf - Class
Arc - Values of the attribute
Leaves contain scores
Each leaf of a decision tree contains informing for SCORING
If classification were to happen 96.5% of training instances are NO new records would be classified as NO
If an estimate were needed 0.965 would indicate NO
Using a tree to…
Select variables
Understand which variables are most important
To produce score and probability
Estimation
To produce ranking
The order is more important than the score
Handling Missing Values
Decision trees can handle missing values by using “Null”
Keeping null is sometimes better than removing records or imputing missing values
Advantage of Decision Tree
Easy to understand how predictions are made (transparent model)
Easy to visualize
Easy to build rules
A tree is a graphical representation of a set of rules that are easy to interpret
Do not require the assumptions of statistical models
Can work without extensive handling of missing data
Variable selection is automatic
What is overfitting?
Statistical models can produce highly complex explanations of relationships between variables
The fit may be excellent
When used with new data(unseen data) models are too complex and do not perform as well as expected
Graphical representation of overfitting
We can fit a polynomial of degree (N-1) to pass through N data points exactly
100% fit → but not useful for unseen data
Regression curve → so rigid it loses generality
Regression Line → Simple to understand and apply

Pruning the Tree
Full trees and complex and OVERFIT data
Pruning is a way of increasing model stability by reducing model complexity