Cue topics TT2 CSC311
 Call Kai
 Learn
 Practice Test
 Spaced Repetition
 Match
 Flashcards
 Knowt Play
1/23

Earn XP
Description and Tags
contains unit from 5-9 with highlevel ideas
24 Terms

2 layer MLP for XOR -6
1. Why is a deep linear network no more expressive than a linear model?
By repeated substitution, any number of linear layers collapses to one.
- deep network whose hidden activations are all linear has the same expressiveness as logistic/ linear regression. - 6

non vectorized back prop -6

vectorized back prop - 6

bias variance decomposition -7

bagging - 7
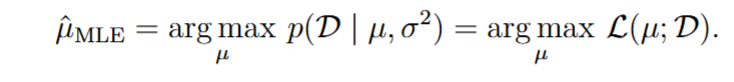
Maxium likelihiid estimation - univariate - 7
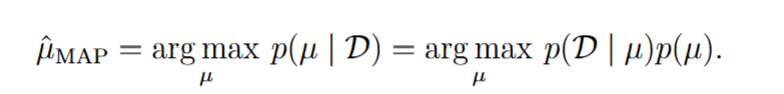
Maxium A posteriori ; univariate 7

Binary Bag of Words - 8
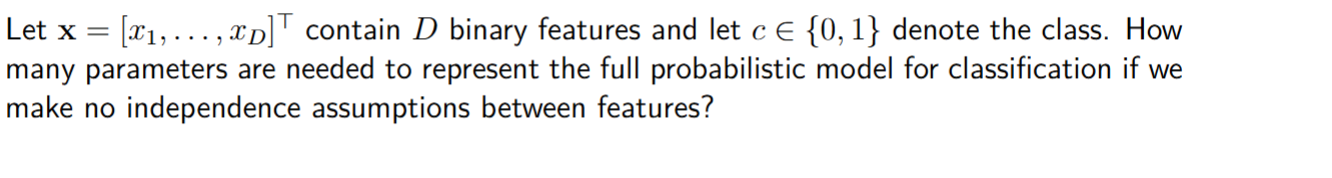
Naive Bayes assumption -8

generative classifier - 8

Compute MLE Naive bayes - 8

Derive MLE naive bayes classifer -8

Inference in a Naive Bayes Classifier-8

Computing MAP of Parameters of Naive Bayes Classifief=r - 8

GDA with One Feature - 9

Computing MLE of Parameters of a Multivariate Gaus-
sian - 9

Computing MLE of Parameters of GDA-9

GDA with Two Features - 9

Drawing the Gaussian contours - 9
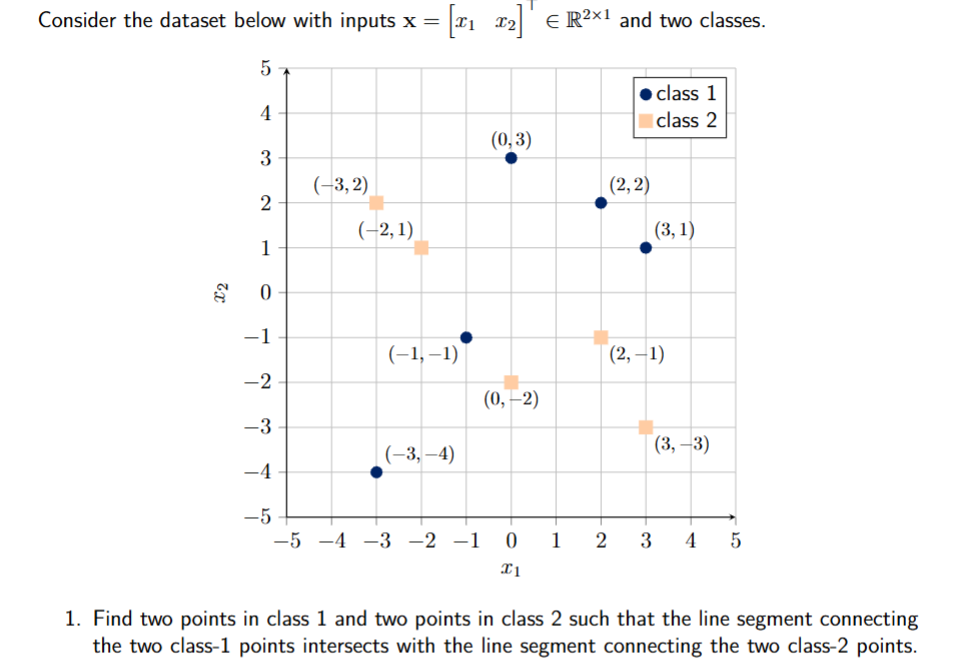
Linear seperability -5

Multilayer Perceptrons - 5

Inference 3 layer MLP - 5
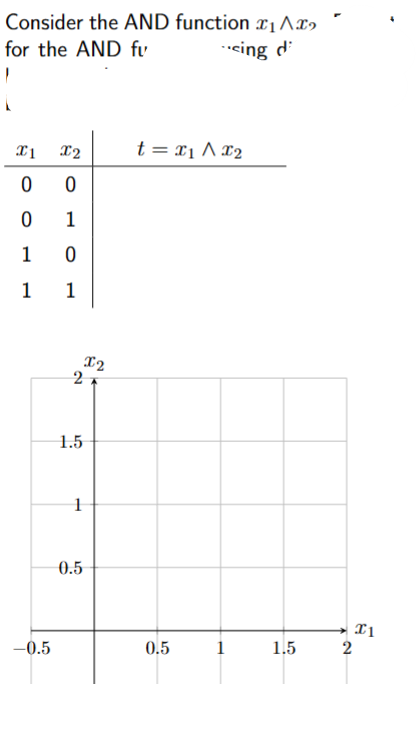
Decision Boundary of Linear Classification Model - 5