Correlational stats
 Call Kai
 Learn
 Practice Test
 Spaced Repetition
 Match
 Flashcards
 Knowt Play
1/56

There's no tags or description
Looks like no tags are added yet.
Name | Mastery | Learn | Test | Matching | Spaced | Call with Kai | Chat |
|---|
No analytics yet
Send a link to your students to track their progress
57 Terms
Intro
We are now looking at the Second category of statistics —- correlational statistics.
correlational statistics were created to work with the relationship between two sets of scores or in other words the relationship between two variables
What is any characteristic of a set of people or things that can vary from Individual case to the next case
variable
Example of scores on the variable
Suppose the students in a history class took a test and each received a history score. Test is a variable, and the scores on this variable are shown in table 7-1
STUDENT | HISTORY TEST SCORE(variable name) |
John | 74 (individual cases) |
Dalra | 88 (individual cases) |
jenny | 82 (individual cases) |
Bill | 91 (individual cases) |
ryan | 79 (individual cases) |
Other examples of variables might be age weight and IQ score. as noted in chapter 3 when we work with a set of scores we identify the set as the “X scores” this means that we are talking about the scores on a variable X. similarly, if we have a set of scores on a second variable we could call these the “Y scores” or the scores on the variable Y.
Pairs of variables
So far in this book we have been working with distribution of scores on one variable at a time. and this chapter we will work with relationship between Pairs of variables. As a matter of fact, in science a great deal of time is devoted to investigating the relationships between Pairs of variables. We might even say that this is the main purpose of science.
Pairs of variables:
physical sciences
In the physical sciences many of these relationship between variables are virtually perfect.
For example, suppose we decide to replicate Galileos famous experiment in the field physics. if we drop weights off the Leaning Tower of Pisa and keep very careful measurements of time (variable X) and distance traveled (variable Y), we would find that the relationship between the two variables can be described almost perfectly by the following equation :
Y= 16X2 or distance travled = 16(time)2
When distance is measured in feet and time is measured in seconds .
If all relationships were this precise, we would have no need for correlational statistics. However, in the behavioral sciences and in many other of human endeavor we usually work with imperfect relationships, and often these relationships cannot be detected without using statistical methods.
Nonetheless, these imperfect relationships are strong enough to be useful. we can use our knowledge of these relationships to make predictions that are much better than mere guesses.
For example, the imperfect relationship between High School grades and college grades, between test scores and work performance, or between educational level and income can be used to make predictions that have practical applications
behavioral sciences and in many other of human endeavor we usually work with what kinds of relationships
imperfect relationships, and often these relationships cannot be detected without using statistical methods.
Nonetheless, these imperfect relationships are strong enough to be useful. we can use our knowledge of these relationships to make predictions that are much better than mere guesses.
For example, the imperfect relationship between High School grades and college grades, between test scores and work performance, or between educational level and income can be used to make predictions that have practical applications
What are the three tasks of correlational statistics
Correlational statistic techniques are used to perform three tasks that could not be done efficiently without them.
to measure the strength of the relationship
accomplished by computing the correlational coefficient
make the best possible predictions
accomplished by finding the regression line
forecast (in advance) the size of a typical prediction error.
accomplished by calculating the standard error of estimate.
The first task of correlational statistics
determine whether a relationship exists between two variables and, if so, to measure the strength of the relationship.
This is accomplished by computing the correlational coefficient
The second task of correlational statistics
make the best possible predictions of one variable from the other, based on our knowledge of the relationship between them. this is accomplished by finding the regression line.
The third task of correlational statistics
The third task is to forecast (in advance) the size of a typical prediction error.
The remainder of this chapter is devoted to the first task, that is of measuring the strength of the relationship between two variables.
MEASURING THE STRENGTH OF THE RELATIONSHIP: A VISUAL APPROACH
Suppose that we are interested in the relationship between High School grades and College grades.
We have followed 10 students through high school and college and have calculated their grade point averages (GPAs).
our results are shown in table 7-2
STUDENT # | X HIGH SCHOOL GPA | Y COLLEGE GPA |
1 | 3.7 | 3.0 |
2 | 2.5 | 2.1 |
3 | 3.5 | 3.3 |
4 | 2.8 | 2.7 |
5 | 3.2 | 3.3 |
6 | 2.6 | 1.8 |
7 | 3.6 | 2.9 |
8 | 2.9 | 2.5 |
9 | 3.4 | 3.2 |
10 | 2.2 | 1.1 |
The scattergram:
In CH 2, we presented graphic techniques for describing a set of scores representing a single variable
In this chapter we present a similar graphic technique for illustrating the relationship between two variable. The technique, developed in the late 1800s by francis galton is called a scattergram (or scatterplot)
Conventions for construction a scattergram.
Remember in chapter 2 we had conventions for making grass to ensure that these visual displays presented the information as efficiently as possible. we also have conventions for constructing a scattergram. A good scattergram should have the following characteristics:
(1): The variable to be used a predictor (e.g., high school GPA) should be placed on the horizontal or X-axis, with an axis label and a numerical scale
(2) The variable to be used as the criterion ( the one you wish to predict) should be placed on the vertical or y-axis, with an axis label and a numerical scale.
(3) the horizontal and vertical axes should be of equal length, using equal sized intervals if possible
(Iv) Each subject (student) should be represented on the scattergram by a dot at the intersection of his scores on the two variables.
In this chapter we present a similar graphic technique for illustrating the relationship between two variable
Who developed in the late 1800s who develeped a technique called a scattergram (or scatterplot)
Francis galton
Conventions for construction a scattergram.
we conventions for constructing a scattergram. A good scattergram should have the following characteristics:
The variable to be used a predictor (e.g., high school GPA) should be placed on the horizontal or X-axis, with an axis label and a numerical scale
The variable to be used as the criterion ( the one you wish to predict) should be placed on the vertical or y-axis, with an axis label and a numerical scale.
the horizontal and vertical axes should be of equal length, using equal sized intervals if possible
Each subject (student) should be represented on the scattergram by a dot at the intersection of his scores on the two variables.
Interpreting a scattergram:
Figure 7-1 is a scattergram of the high school GPA and college gpa pairs for 10 students shown in table 7-2. we can easily see in this scattergram that the high school GPA and college gpa are strongly related, because the points representing the students seem to string out along a line.
STUDENT # | X HIGH SCHOOL GPA | Y COLLEGE GPA |
1 | 3.7 | 3.0 |
2 | 2.5 | 2.1 |
3 | 3.5 | 3.3 |
4 | 2.8 | 2.7 |
5 | 3.2 | 3.3 |
6 | 2.6 | 1.8 |
7 | 3.6 | 2.9 |
8 | 2.9 | 2.5 |
9 | 3.4 | 3.2 |
10 | 2.2 | 1.1 |
Table 7-2
And the scattergram and figure 7-2 we have roughly estimated and drawn in a line that minimizes the errors around itself (that is, we have drawn a line that minimizes the vertical distances of each point from the line). This line can be used to make rough predictions of college GPA from high school gpa.
For example, suppose we know that Ryan's high school GPA is 3.5. to predict his college GPA We locate 3.5 on the horizontal axis in figure 7-2; then we determine the vertical distance from this point on the horizontal axis to the line. This vertical distance is predicted college gpa, for someone with a high school GPA of 3.5.
Note that while the line and figure 7-2 represents predicted College GPAS, the dots represent the actual College GPAs. So when the dots string out closely along the line, the predictions are more accurate than when the dots are more widely scattered around the line. in fact, this is how we can visually determine the strength of the relationship.
In a strong relationship the dots of the scattergram string out closely along the line;
In a weak relationship the dots are scattered widely around a line.
When there is no relationship the dots form a random pattern and no good prediction line can be found. figure 7-3 showed several scattergrams illustrating different degrees of relationship .


In a ____ relationship the dots of the scattergram string out closely along the line
strong relationship
In a ___ relationship the dots are scattered widely around a line.
weak relationship

When there is ____ relationship the dots form a random pattern and no good prediction line can be found.
no relationship

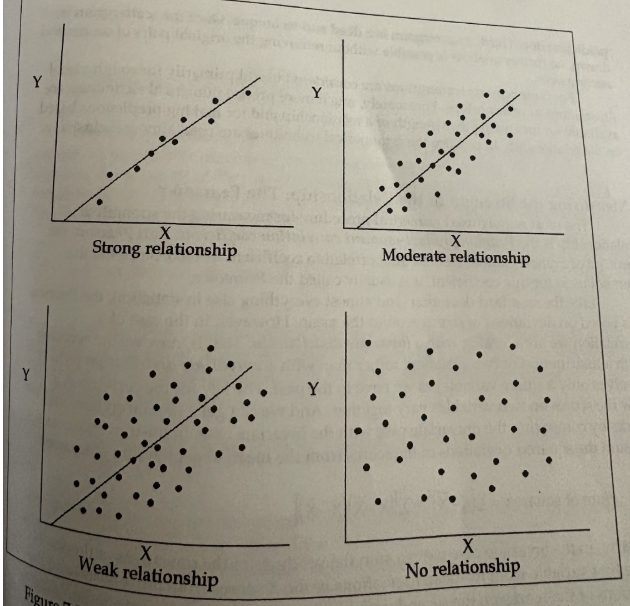
Image of scattergrams with different degrees of relationships
Image of scattergrams with different degrees of relationships
Advantages and limitations of scattergrams:
This graphic method provides a good, but rough, visual illustration of an imperfect relationship between a pair of variables.
A scattergram summarizes the nature of the relationship, this information can be grass quickly by someone without specialized training, and the very rough predictions made from the scattergram are better than simply guessing
On the other hand, there are also some serious drawbacks associated with scattergrams that limit their usefulness.
First, constructing a scattergram can be very laborious and time consuming, especially when a large number of pairs of scores are involved.
Second, a scattergram is imprecise. the assessment of the strength of all relationship can only be a rough estimate. likewise, the location and angle of the prediction line can only be roughly approximated on a scattergram —- each person would draw a different prediction line.
Third, A scattergram is a dead end technique. once the scattergram is wrong, no further analysis is possible without retrieving the original pairs of scores and starting over.
For these reasons scattergrams are considered useful primarily for rough visual illustrations of relationships. fortunately, much more precise numerical techniques are available for measuring the strength of a relationship and for making predictions based on the relationship. and practice these numerical techniques are used almost exclusively.
Advantages of scattergrams
This graphic method provides a good, but rough, visual illustration of an imperfect relationship between a pair of variables.
A scattergram summarizes the nature of the relationship, this information can be grass quickly by someone without specialized training, and the very rough predictions made from the scattergram are better than simply guessing
limitations of scattergrams
First, constructing a scattergram can be very laborious and time consuming, especially when a large number of pairs of scores are involved.
Second, a scattergram is imprecise. the assessment of the strength of all relationship can only be a rough estimate. likewise, the location and angle of the prediction line can only be roughly approximated on a scattergram —- each person would draw a different prediction line.
Third, A scattergram is a dead end technique. once the scattergram is wrong, no further analysis is possible without retrieving the original pairs of scores and starting over.
For these reasons scattergrams are considered useful primarily for rough visual illustrations of relationships. fortunately, much more precise numerical techniques are available for measuring the strength of a relationship and for making predictions based on the relationship. and practice these numerical techniques are used almost exclusively.
MEASURING THE STRENGTH OF THE RELATIONSHIP: THE PEARSON r
The most widely used numerical procedure for measuring the strength of a relationship is the
Pearson product-moment correlation coefficient.
Who is the the protoge of Francis galton, created this correlation coefficient(Pearson product-moment correlation coefficient) in 1866.
KARL PEARSON
MEASURING THE STRENGTH OF THE RELATIONSHIP: THE PEARSON r
The most widely used numerical procedure for measuring the strength of a relationship is the Pearson product-moment correlation coefficient.
KARL PEARSON, the protoge of Francis galton, created this correlation coefficient in 1866. Since r is the symbol used for this coefficient, it is usually called the Pearson r
The Pearson R is based on deviations of scores around the mean.
However, in the case of correlation we are working with a bivariate distribution.
That is, now we are working with a distrubution of two variables, rather than with a univariate distribution (which involves only a single variable) as we have in the past
The key for the correlation is how the scores on two variables vary together. And we can get a handle on how this works by comparing the univariate case with the bivariate case. In the univariate case we sum the squared deviations of scores from the mean to get the sum of squares.
Similarly, in bivariate case we can sum the products of the deviance of the scores on the first variable from its mean (deviations of the X scores from the X mean) and the deviations of the scores on the second variable from its mean (devations of the Y scores from the Y mean) to get the cross product
Next, We average these values. In the univariate case we divide by the N (the number of scores) to get the variance:
Similarly, in the bivariate case be divide by N (the number of pairs of scores ) to get the covariance:
While the variance gives us a measure of variation in a single variable, the covariance shows how much variation is shared by the two variables. Now we can compare this measure of the shared variance with the variances of the two individual variables by dividing the covariance by the standard deviations of the two variables. This value is the correlation coefficient
In effect, by dividing the standard deviations of the individual variables we have standardized the scores. Remember that the deviation of a raw score from the mean comma divided by the standard deviation is how we find the standard (z) score. So our correlational formula reduces to:
So it turns out that our measure of correlation is simply the average of the products of the X scores expressed as z-scores and the Y scores expressed the z-scores.
this standard score formula for the correlation coefficient is simple to understand, but labor is to calculate. Therefore we prefer to use the following raw score formula that is much easier to compute using hand calculator ( even though it looks more complex):
Where X is the sum of X scores, Y is the sum of the Y scores, X2 is the sum of the squared X scores, Y2 is the sum of the squared Y scores, XY is the sum of products of each pair of X and Y scores, and N is the number of pairs of scores. In this book we will use the raw score formula whenever we calculate the Pearson r correlation coefficient.
Pearson product-moment correlation coefficient.
What is the symbol used for this coefficient, it is usually called the ______ __
r, Pearson r
The Pearson R is based on deviations of scores around the mean.
However, in the case of correlation we are working with a …
bivariate distribution.
That is, now we are working with a distrubution of two variables, rather than with a univariate distribution (which involves only a single variable) as we have in the past
What is a birvariate distribution?
working with a distrubution of two variables
What is univariate distribution
involves only a single variable (as we have used in the past)
The key for the correlation is…
how the scores on two variables vary together.
And we can get a handle on how this works by comparing the univariate case with the bivariate case. In the univariate case we sum the squared deviations of scores from the mean to get the sum of squares.

Similarly, in bivariate case we can sum the products of the deviance of the scores on the first variable from its mean (deviations of the X scores from the X mean) and the deviations of the scores on the second variable from its mean (devations of the Y scores from the Y mean) to get the ……
cross product

formula for the sum of squares
formula for the sum of squares

formula for cross product
formula for cross product
Similarly, in bivariate case we can sum the products of the deviance of the scores on the first variable from its mean (deviations of the X scores from the X mean) and the deviations of the scores on the second variable from its mean (devations of the Y scores from the Y mean) to get the cross product
Next, We…
We average these values. In the univariate case we divide by the N (the number of scores) to get the variance:
Similarly, in the bivariate case be divide by N (the number of pairs of scores ) to get the covariance:

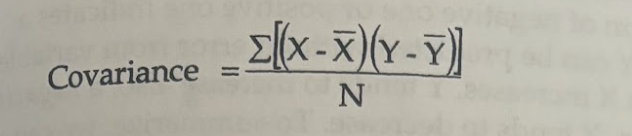
formula for covariance
formula for covariance
While the variance gives us a measure of variation in a single variable, the covariance shows how much variation is shared by the two variables. Now we can compare this measure of the shared variance with the variances of the two individual variables by dividing the covariance by the standard deviations of the two variables. This value is the…..
correlation coefficient

variance gives us a measure of variation in a
single variable
covariance shows how much variation is shared by
two variables

In effect, by dividing the standard deviations of the individual variables we have standardized the scores. Remember that the deviation of a raw score from the mean comma divided by the standard deviation is how we find the standard (z) score. So our correlational formula reduces to:
So our correlational formula reduces to:

So it turns out that our measure of correlation is simply the average of the products of the X scores expressed as z-scores and the Y scores expressed the z-scores.
this standard score formula for the correlation coefficient is simple to understand, but labor is to calculate. Therefore we prefer to use the following raw score formula that is much easier to compute using hand calculator ( even though it looks more complex):
image raw score formula formula for correlation coeffcient below
raw score formula for correlation coeffcient , image
Where (signma sign) X is the sum of X scores
(sigma sign)Y is the sum of the Y scores,
(sigma sign)X2 is the sum of the squared X scores,
(sigma sign)Y2 is the sum of the squared Y scores,
(sigma sign)XY is the sum of products of each pair of X and Y scores
N is the number of pairs of scores. In this book we will use the raw score formula whenever we calculate the Pearson r correlation coefficient.

Interpreting correlations:
The possible values of the correlation coefficient range from negative one to zero positive to positive one.
A correlation of zero indicates no relationship between the two variables. A correlation of negative one or positive one indicates a perfect relationship in which variable Y can be predicted without error from variable X.
A positive correlation indicates that as X increases, Y tends to increase also;
A negative correlation indicates that as X increases, Y tends to decrease. To summarize we can say that about the absolute value of a correlation coefficient indicates the strength of the relationship and its sign tells us the direction of the relationship
Table 7-3 provides some general rules of thumb for interpreting correlations of various sizes. Later we will develop a more sophisticated system for interpreting correlations, but for now this table can serve as our interpretation guide
Rules of thumb for interpreting correlations of various sizes
Correlation coefficient
Strength of relationship
Accuracy or prediction
.00-.29
Nonexistent or weak
poor
.30–.59
moderate
Fairly good classification into rough group (e.g. low versus high scores)
.60-.89
strong
Very large prediction errors
.90-1.00
Very strong
Very accurate predictions
The possible values of the correlation coefficient range from..
negative one to zero positive to positive one.
A correlation of zero indicates …
no relationship between the two variables
A correlation of negative one or positive one indicates, what kind of relationship, in which variable Y can be predicted without error from variable X.
a perfect relationship
A positive correlation indicates that as …
X increases, Y tends to increase also
A negative correlation indicates that as ….
X increases, Y tends to decrease. To summarize we can say that about the absolute value of a correlation coefficient indicates the strength of the relationship and its sign tells us the direction of the relationship
Rules of thumb for interpreting correlations of various sizes
Rules of thumb for interpreting correlations of various sizes
Correlation coefficient | Strength of relationship | Accuracy or prediction |
|---|---|---|
.00-.29 | Nonexistent or weak | poor |
.30–.59 | moderate | Fairly good classification into rough group (e.g. low versus high scores) |
.60-.89 | strong | few large prediction errors |
.90-1.00 | Very strong | Very accurate predictions |
identify the strength of relationship & Accuracy or prediction of this correlation coeffcient : 00-.29
Strength of relationship | Accuracy or prediction |
|---|---|
Nonexistent or weak | poor |
identify the strength of relationship & Accuracy or prediction of this correlation coeffcient : .30–.59
Strength of relationship | Accuracy or prediction |
|---|
moderate | Fairly good classification into rough group (e.g. low versus high scores) |
identify the strength of relationship & Accuracy or prediction of this correlation coeffcient : .60-.89
Strength of relationship | Accuracy or prediction |
|---|
strong | few large prediction errors |
identify the strength of relationship & Accuracy or prediction of this correlation coeffcient : .90-1.00
Strength of relationship | Accuracy or prediction |
|---|
Very strong | Very accurate predictions |

Figures 7-4 through 7-8 show scattergrams of correlations of various sizes. Note that the scartttergram in figure 7-8 shows a negative correlation. This negative correlation is easily distinguished by the fact that as X increases, Y decreases (the scattergram slopes down from left to right), while the remaining figures illulstate positive relationships in which X and Y tend to increase together (and the scattergrams slope up from left to right)
images of figure 7-4 through 7-8 show scattergrams