PSY301 Lecture 13: Tests of frequency: Chi-square and Log-linear analysis
 Call Kai
 Learn
 Practice Test
 Spaced Repetition
 Match
 Flashcards
 Knowt Play
1/8

There's no tags or description
Looks like no tags are added yet.
9 Terms
Categorical outcomes
Sometimes we have data consisting of the frequency of cases falling into unique categories
Examples:
Number of people voting for different politicians
Numbers of students who pass or fail their degree in different subject areas.
Number of patients or waiting list controls who are ‘free from diagnosis’ (or not) following treatment.
Number of people who are cured or not after an intervention.
Number of people who receive (vs not) an intervention.
Chi Square (χ2 )
A non-parametric stats to assess relationships between two categorical variables.
Is the distribution of categories significantly different from what we’d expect by chance?
Does food (vs. affection) effectively makes cats dance (vs. not)?
How does it work? By comparing observed frequencies with expected frequencies under the null hypothesis.
Question: Do the counts we observed differ from the counts we’d expect if nothing were going on?
Two common forms:
Goodness-of-fit: One variable. Do the observed proportions match a hypothesized distribution?
Test of independence: Two variables. Are they associated, or independent?
We will focus on the Test of independence.
Chi Square (χ2 ) - How does it work?
H0 : The two variables are independent (no association)
“Driver’s age category (under 26 vs over 26 years old) is not associated with handheld phone use while driving (yes vs no)”
H1 : The two variables are associated.
“Driver’s age category (under 26 vs over 26 years old) is associated with handheld phone use while driving (yes vs no)”
Processing the analysis
Step 1: Build a contingency table of observed frequencies (O)
Step 2: Calculate the Expected Frequencies (E) if H0 were true: E = (row total X column total) / N
Step 3: Measure how far O departs from E using Chi-square formula: χ 2 = Σ (O – E)2 / E
The larger the χ 2 , the bigger the mismatch, and H0 becomes less plausible. Accept H1
Degree of freedom (df) and decision
df = (rows – 1) X (column – 1). For a 2 X 2 table, the df would be (2-1) X (2-1) = 1.
Compare χ 2 to the χ 2 from the table with the df.
Χ2 tells us whether there is an association, not how strong it is.
The contingency table (Observed and Expected frequencies)

Effect size (Phi)


Tells us how much more (or less) likely an event is in one group compared to another.
e.g., we want to look at the odds ration of younger people (vs older) that influences the (mis)use of mobile phone while driving.

χ2 is non-directional, so we need the percentages to see where the difference lies.

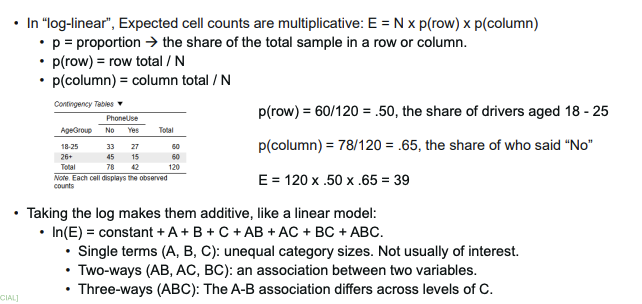
Log-linear Analysis
• An extension of chi-square analysis to three or more categorical variables.
• It models the cell counts of a multi-way contingency table.
• Question: Which variables are associated, and does an association depend on a third variable (interaction)?
• There is no DV or IV. All variables are treated symmetrically.
• Why not just running Ch-square multiple times to test the association with each variable?
It inflates Type I error and can’t detect three-ways patterns (interaction). Loglinear analysis tests everything in one model.

Log linear analysis: Start saturated, then simplify


