DATS 2103 Exam 1
 Call Kai
 Learn
 Practice Test
 Spaced Repetition
 Match
 Flashcards
 Knowt Play
1/39

There's no tags or description
Looks like no tags are added yet.
Name | Mastery | Learn | Test | Matching | Spaced | Call with Kai | Chat |
|---|
No analytics yet
Send a link to your students to track their progress
40 Terms
We estimate the linear regression coefficients by minimizing the
RSS (residual sum of squares)
The standard deviation of the error and accuracy of the model is measured using
RSE (residual standard error)
The ____ can be used to reject the null hypothesis if it is less than 0.05.
p-value
Performing ____ ensures that every observation is selected for testing data at least once.
cross-validation
The _____ is reported in units of Y 2
MSE (mean squared error)
The _____ approach is a non-parametric method that makes a prediction based on the closest training observations.
K nearest neighbors
Linear Discriminant Analysis uses a ____ to separate observations into distinct classes
decision boundary
The _____ measures the probability that a randomly chosen observation belongs to class k.
prior probability
Performing _____ to sub-select predictors requires the user to check every possible combinations of predictors (2p).
best subset selection
The _____ is unsupervised method used to transform the predictors (p) to a linear combination of the predictors (M, p ≥ M).
PCA (principle component analysis)
A ______ is a location where our coefficients and functions change.
knot
The _____ is a combination of step functions and polynomial regression
regression spline
The Decision Tree based model can be improved upon by using bagging and sub-selecting predictors at each split, typically called
random forest
The goal of splits in trees is to produce homogeneous child nodes, often called
node purity
We can relax the additive assumption of linear regression by adding interaction terms.
T
Linear regression is applicable to datasets where p is larger than n.
F
Naive Bayes classifiers assumes that all predictors are independent within classes
T
Classifiers typically return a probability that a given observation belongs to class k.
T
It is expected that the training error rate is lower than the testing error rate.
T
A confusion matrix is used to assess accuracy for classification and regression models.
F
It is good practice to prevent data leakage by reusing the same sample in both training and testing.
F
Both Ridge Regression and Lasso use a shrinkage penalty to regularize the coefficients to reduce the impact of the predictor on the model
T
Forward and Backward Stepwise Selection are guaranteed to find the best possible combinations of predictors
F
Cross Validation is often used to find the most optimal parameters.
T
Basis Functions are fixed, known functions (bk(X)) that transform X to allow us to use statistical tools like Standard Errors and Coefficient estimates.
T
For splines, it is best practice to use fewer knots to increase flexibility in regions where it may be necessary.
F
Generalized Additive Models allow us to use more than one predictor in our model
T
Out of Bag Error calculated on samples not included in the bagging is an acceptable estimation of the models performance
T
Tree based methods do not have any linearity assumptions between the predictors and the response.
T

ridge regression

smoothing splines

linear regression

lasso regression

linear regression
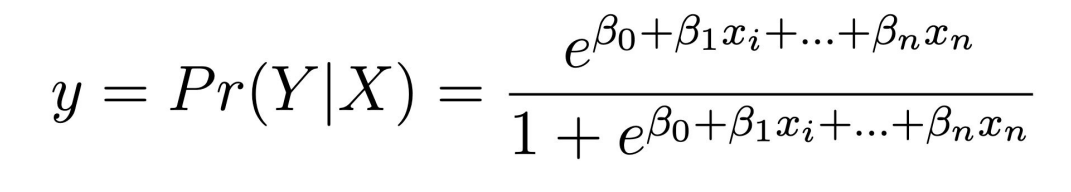
logistic regression

ridge regression

polynomial regression

step functions

regression splines

lasso regression