Daily report
‘22/12/23
Cleaning the files
Because the species were mixed in the files, redid ^^Coding_challenge_4_TENT4A_PAPD7.py^^ and ^^Coding_challenge_4_TENT4B_PAPD5.py^^ on my files and got ^^NEW_(order)_(gene).fas^^
Ran ^^Coding_challenge_5.py^^ and replaced the Sequences that were too short
[ ] Edited ^^Coding_challenge_5.py^^ using Biopython pairwise
Getting new species
- Take the NCBI accession number from ^^NEW_(order)_(gene).fas^^ and used blast to get csv and fasta file
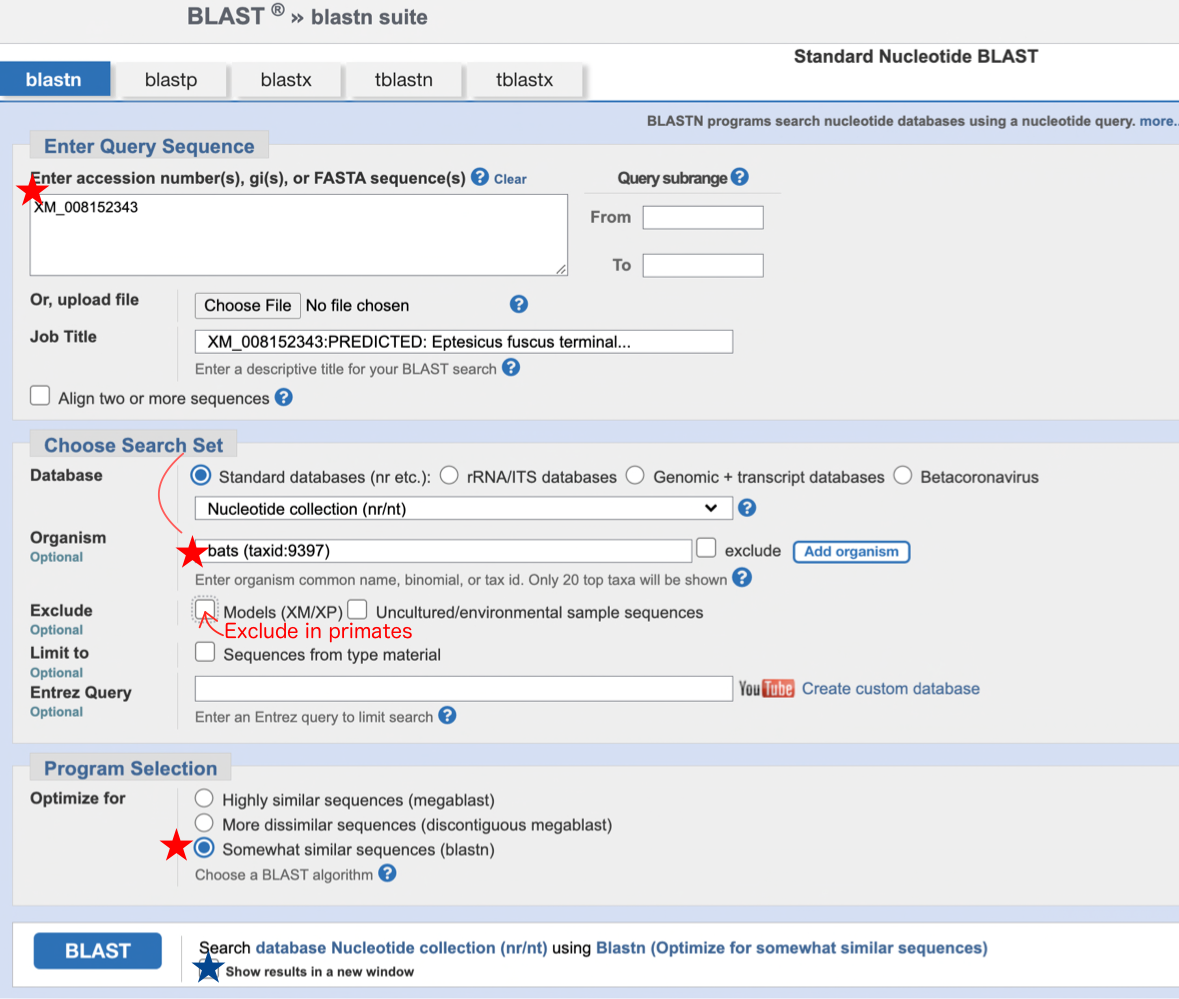
- List the species that weren’t in the fasta file
‘22/12/26
- Make ^^Coding_challenge_5_draft.py^^ compare with the longest sequence using dict key values
  d1={record.id:record.seq for record in SeqIO.parse(file, "fasta")}
  d2={record.id:len(record.seq) for record in SeqIO.parse(file, "fasta")}
  d2=sorted(d2.items(), key=lambda x:x[1],reverse=True)

  #df_d1=pd.DataFrame.from_dict(d1) ←this gave an error (ValueError: All arrays must be of the same length)
  df_d2 = pd.DataFrame(d2)
  ```

## ‘22/12/27


> ## Finish adding species

* Finished adding species acquired from BLAST to each fasta file

### Converting a text file into a list by splitting the text on the occurrence of ‘.’.
python
opening the file in read mode
my_file = open("file1.txt", "r")
reading the file
data = my_file.read()
replacing end of line('/n') with ' ' and
splitting the text it further when '.' is seen.
data_into_list = data.replace('\n', ' ').split(".")
printing the data
print(data_into_list) my_file.close() ```
- Left only the Longest sequence in the file. ^^NEW_12_27_(order)_(gene).fas^^ has only one sequence per species.