Transcriptomics
Fundamentals of Transcriptomics and RNA Biology
Definition of Transcriptomics:
Transcriptomics is the study of the complete set of RNA molecules (transcripts) expressed by an organism, tissue, or cell type under specific developmental stages or physiological conditions.
The Central Dogma of Molecular Biology:
Genetic information flows sequentially from deoxyribonucleic acid () to ribonucleic acid () via transcription, and subsequently from to protein via translation.

Primary RNA Classifications:
Coding RNA:
Messenger RNA (): Linear single-stranded RNA transcripts that convey genetic code from nuclear to ribosomal translation machinery for polypeptide synthesis.
Non-coding RNA (): Functional RNA molecules that do not translate into proteins but mediate core catalytic, infrastructural, and regulatory functions:
Ribosomal RNA (): Catalytic and structural components that coordinate with ribosomal proteins to assemble ribosomes and synthesise polypeptides.
Transfer RNA (): Adaptor molecules that decipher codons and deliver corresponding amino acids to the nascent polypeptide chain during translation.

Major Classes of Regulatory Non-Coding RNAs:

RNA Extraction, Isolation, and Small RNA Purification
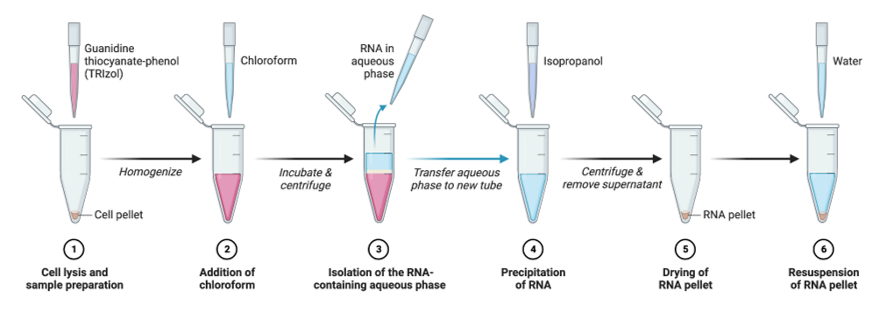
Total RNA Extraction via Guanidine Thiocyanate-Phenol (TRIzol):
Step 1: Cell Lysis and Sample Preparation:
Biological tissues or cell pellets are homogenized (thoroughly broken down and mixed) in a monophasic solution of guanidine thiocyanate and phenol (TRIzol / TRI Reagent) to disrupt cell membranes and dissolve intracellular components while inhibiting endogenous ribonucleases () (stopping the RNA-destroying enzymes that are naturally present inside a cell or tissue)
Step 2: Phase Separation Initiation:
Addition of chloroform induces phase separation following thorough mixing.
Step 3: Centrifugation and Phase Isolation:
Incubation and centrifugation separate the mixture into three phases: a lower red organic phase (containing proteins), an interphase (containing ), and an upper transparent aqueous phase containing total .
The RNA-containing aqueous phase is carefully transferred into a clean tube.
Step 4: RNA Precipitation:
Pure isopropanol is added to the aqueous phase to precipitate total .
Step 5: Pellet Sedimentation and Washing:
Centrifugation pellets the insoluble ; the isopropanol supernatant is decanted, and the pellet is air-dried.
Step 6: Pellet Resuspension:
The purified pellet is resuspended in nuclease-free water.
End-to-End Small RNA Purification and Sequencing Workflow ():

Step 1: Sample Collection and Total RNA Extraction:
Material sources: Plant tissues (leaves, seeds), animal tissues, or in vitro cultured cells.
Common kits/reagents: QIAGEN miRNeasy Mini/Micro Kit, Norgen Total RNA Purification Kit, TRIzol / TRI Reagent.
Plant-specific procedural modifications: Polysaccharides and polyphenol compounds co-purify with nucleic acids and potently inhibit downstream enzymatic ligations. Inclusion of polyvinylpyrrolidone () and during extraction is mandatory. Tissues from crops such as rice, wheat, oat, and tef require the miRNeasy Plant protocol or modified CTAB/TRIzol protocols. Plants characteristically exhibit abundant small interfering RNAs (), elevating library complexity.
Step 2: Quality Assessment of Extracted RNA:
Fluorometric Concentration: Measured via Qubit fluorometer using the RNA HS (High Sensitivity) assay.
Spectrophotometric Purity: Evaluated on a NanoDrop spectrophotometer; optimal pure RNA exhibits an ratio of approximately .
Electrophoretic Integrity: Profiled using an Agilent Bioanalyzer with RNA Nano or RNA Pico chips. Although the RNA Integrity Number () is less critical for small RNA sequencing than for intact sequencing, high-integrity input RNA ensures robust library representation.
Step 3: Small RNA Enrichment ():
Method A (Gold Standard): Gel-based size selection: Separation across a denaturing urea-polyacrylamide gel () followed by targeted physical excision of the band corresponding to .
Method B: Commercial spin-column kits (Accelerated workflow): QIAGEN miRNA Isolation Kit, Zymo RNA Clean & Concentrator, NEB Monarch RNA Cleanup.
Method C: Solid Phase Reversible Immobilization (SPRI) magnetic bead selection: Selective bead-to-sample volumetric ratios bind and remove high-molecular-weight RNAs (, ), leaving small RNAs in suspension.
Step 4: Yield of Purified Small RNA:
Generates isolated fractions of enriched species (, , , and -derived fragments) depleted of large and .
Step 5: Library Preparation:
Standard biochemical cascade: Sequential adapter ligation, adapter ligation, reverse transcription to generate single-stranded , followed by high-fidelity amplification.
Library size selection: Purifies the amplified product to isolate fragments of ~ (accounting for the insert plus flanking adapter constructs).
Commercial library kits: Illumina TruSeq Small RNA, QIAseq miRNA Library Kit, NEBNext Small RNA, NEXTFLEX Small RNA-seq Kit.
Step 6: Library Quality Control:
Validated on an Agilent Bioanalyzer using a High Sensitivity DNA Chip or an Agilent TapeStation D1000 screen.
Confirms a narrow, distinct electrophoretic peak centered at ~
Step 7: High-Throughput Sequencing:
Conducted on Illumina platforms (e.g., NextSeq, NovaSeq) using single-end sequencing protocols, typically with read lengths of .
Step 8: Downstream Computational Analysis:
Successive pipeline: Raw read quality control and adapter trimming Genome alignment against a reference sequence Quantification of specific small RNA populations (, , ) Differential expression statistical modeling Functional annotation and target prediction.
Complementary DNA (cDNA) Synthesis
Definition and Properties of cDNA:
Complementary () is synthetic DNA synthesized (the process of creating or building new strands of deoxyribonucleic acid (DNA)) enzymatically from an template via the enzyme reverse transcriptase.
Because eukaryotic mature (a fully processed molecule of messenger RNA that is ready to be translated into proteins by the cell's ribosome) undergoes post-transcriptional splicing, derived from mature contains exclusively coding exons without intervening non-coding introns.
Biochemical Synthesis Mechanism:
Annealing: Mature eukaryotic molecules carrying a polyadenylated tail () are hybridized with a complementary synthetic oligo-dT primer ().
First-Strand cDNA Synthesis: Reverse transcriptase utilizes the hybridized oligo-dT primer to polymerize a complementary antisense single-stranded strand moving in the to direction.
Second-Strand cDNA Synthesis: DNA polymerase synthesizes the complementary sense strand using the first-strand as a template, producing a double-stranded molecule suitable for cloning or sequencing.

Microarray Technology and Applications
Historical Context and Operating Principles:
First published in 1995.
Microarrays quantify the relative abundance of a predetermined set of target transcripts based on nucleic acid hybridization.
Substrates consist of solid matrices (microscopic glass slides, specialized polymers, or micro-beads) onto which high-density grids of single-stranded synthetic oligonucleotide probes are covalently tethered.
Microarrays = a laboratory tool used to detect and measure the expression of thousands of genes or analyze genetic variations (like single-nucleotide polymorphisms or SNPs) all at the same time on a small solid surface, such as a glass slide or silicon chip
Comparative Two-Channel Microarray Experimental Workflow:
Sample Preparation: Extraction of from distinct experimental groups (e.g., biological females versus males).
Labeling: is reverse-transcribed into using reverse transcriptase and random hexamer priming, simultaneously incorporating distinct fluorophores (e.g., green fluorophore for female-derived , red fluorophore for male-derived ).
Hybridization: Labeled populations are pooled and incubated on the microarray substrate to anneal competitively to complementary immobilized oligonucleotide probes.
Washing: Microarray substrates are washed under stringency conditions to eliminate unhybridized and non-specifically bound nucleic acids.
Laser Acquisition and Signal Processing: Dual-wavelength confocal laser scanning excites fluorophores at respective absorption maxima, generating image files (several megabytes in size) showing spot-specific fluorescent emission intensities.
Bioinformatic Classification: Processed text files compute differential intensity ratios, categorizing loci into female-biased, male-biased, or non-sex-biased expression profiles.


Limitations of Microarray Architectures:
Microarrays are closed systems limited to interrogated transcripts; unannotated genes, novel isoforms, or sequences lacking complementary probes on the array cannot be quantified.
Microarrays for Single Nucleotide Polymorphism (SNP) Interrogation:
Probe Design: Substrates are synthesized with immobilized allele-specific oligonucleotides terminating at or spanning targeted single-nucleotide variants (, , , or ).
Genomic Breeding and Marker Pipelines:
In Silico Mining: Querying public repositories (dbSNP database) identifies prospective pools.
Primary Selection (Validation): High- to medium-throughput validation assays screen candidate germplasm pools against identified .
Secondary Selection (On-farm Selection): Medium- to low-throughput screening selects validated markers associated with specific Quantitative Trait Loci () on targeted chromosomes (e.g., chromosome 1 and chromosome 4 in swine models) for genomic selection and association mapping.


RNA Sequencing (RNA-Seq) Methodology and Comparison to Microarrays
RNA-Seq Technology Overview:
First published in 2006.
High-throughput next-generation sequencing () enables direct base-by-base sequencing of fragments generated from cellular transcriptomes.
Library Construction: Total or fractionated is isolated, sheared into fragments, converted to double-stranded , and end-repaired; sequencing adaptors are ligated to one or both termini.
Sequencing Strategy: High-throughput sequencing yields either single-end reads (sequenced from one terminus) or paired-end reads (sequenced inward from both termini), outputted into standard text-based FASTQ files.
Read Dimensions: Typically ranges from to on short-read platforms.
Signal Fidelity: Exhibits low optical and hybridization background noise compared to microarrays.

Technological Benchmark: RNA-Seq vs. Microarrays (DOI: 10.1371/journal.pcbi.1005457):

Comprehensive Survey of High-Throughput RNA-Seq Platforms:
454 (Roche):
Release year: 2005.
Typical read length: .
Maximum throughput per run: .
Single-read accuracy: .
Primary application: Historical early-generation RNA-seq.
Illumina:
Release year: 2006.
Typical read length: .
Maximum throughput per run: .
Single-read accuracy: .
Primary applications: Differential gene expression (), bulk transcriptome sequencing, single-cell RNA-seq ().
Ion Torrent:
Release year: 2010.
Typical read length: .
Maximum throughput per run: ~.
Single-read accuracy: ~.
Primary application: Targeted transcriptomics.
PacBio HiFi:
Release year: 2011.
Typical read length: .
Maximum throughput per run: .
Single-read accuracy: .
Primary applications: Full-length transcript sequencing without assembly, complex isoform profiling.
Oxford Nanopore:
Release year: 2014.
Typical read length: to .
Maximum throughput per run: Up to several .
Single-read accuracy: .
Primary applications: Direct native RNA sequencing, comprehensive isoform identification, RNA modification mapping.
Sequencing Quality Control and Transcriptome Assembly
Sequencing Quality Control Metrics and Filtering:
Phred Quality Scoring: Every called base is assigned an error probability score ranging from to , where .
Quality Score Threshold: Base calls must exceed a Phred score threshold of to be retained without filtering.
FastQC Metric Interpretation:
Blue curve represents the mean quality score at each consecutive base pair window across the read length.
Central red line inside each yellow rectangular box denotes the median quality score.
Yellow box denotes the interquartile range (, to percentile).
Whiskers demarcate the boundary of the and percentiles.
Green horizontal background indicates high quality (); yellow background indicates acceptable warning zones (); red background indicates poor quality ().
Trimming and Preprocessing Actions: Low-quality bases located at read termini (notably where base qualities degrade below threshold, such as positions ), along with adapter sequences and experimental barcodes, must be trimmed prior to alignment.

De Novo Transcriptome Assembly:
Reconstructs transcripts directly from overlapping sequence reads without aligning to a reference genome.
Core challenges include resolving complex contigs, eliminating chimeric assembly artifacts and sequencing errors, and optimizing algorithmic computational memory.
Assembly Quality Assessment Metrics:
Median contig length.
Total assembled contig count.
Metric Definition: Given an assembled contig dataset ordered by descending length, represents the sequence length of the shortest contig such that all contigs of equal or greater length collectively constitute at least of the total assembly length.
Genome-Guided Transcriptome Assembly:
Aligns sequenced reads directly against an established reference genome, using mapped coordinates to reconstruct splicing isoforms.
Follows alignment strategies similar to whole-genome sequencing workflows.
Quality is benchmarked by evaluating de novo structural integrity parameters and verifying alignment congruency against known, validated transcript annotations.
Gene Expression Quantification and Mathematical Normalization
Read Count Quantification Principles:
Quantifies transcriptional variations triggered by experimental conditions, genetic interventions, or disease states.
Computes the aggregate tally of reads aligned to each specific genetic locus.
Raw read counts cannot be directly compared across different genes or experiments without mathematical normalization for sequencing depth and gene length.
Library Size and Sequencing Depth Normalization:
Fragments Per Million Mapped Reads (): Corrects fragment abundance based on total mapped library size in millions.
Reads Per Million Mapped Reads () / Counts Per Million (): Normalizes raw counts against the total number of reads sequenced per sample.
Gene Length Normalization:
Longer genes generate a proportionally higher number of fragmented sequencing reads than shorter genes expressed at identical molar concentrations.
Dividing depth-normalized values by feature length (in kilobases) generates normalized expression values.
Formulas for Expression Normalization:
Reads Per Kilobase Million (): Applied exclusively to single-end RNA-seq datasets:
Fragments Per Kilobase Million (): Applied to paired-end RNA-seq datasets, where two paired reads originate from a single continuous fragment, preventing double-counting:
Bioinformatics Pipelines for Differential Gene Expression (DGE)
The Tuxedo Suite / Galaxy Pipeline Architecture:
Bowtie: Memory-efficient, ultra-fast short-read aligner based on the Burrows-Wheeler Transform; indexes the reference genome (
.fafile) and aligns short reads.TopHat: Splicing-aware aligner that utilizes Bowtie alignments to identify exon-exon splice junctions and map reads spanning introns across the genome.
Cufflinks: Assembles aligned reads into individual transcripts, constructs parsimonious isoform models, and computes relative expression abundance based on gene annotations (
.gtffile).Cuffmerge: Merges assembled transcript structures across multiple experimental conditions and replicates into a unified transcriptome assembly.
Cuffdiff: Calculates differential expression between comparative experimental conditions (e.g., condition versus condition ), testing significance through statistical models of transcript abundance.
CummeRbund: Downstream R-based computational environment designed to parse, index, and visualize Cuffdiff statistical output files.

Modern Count-Based Differential Gene Expression Pipeline:
Sequence Ingestion: Input raw paired-end or single-end reads in FASTQ format.
Splice-Aware Sequence Alignment: Reads are mapped against the reference genome using modern high-efficiency aligners (HISAT2, STAR, TopHat2, or Bowtie 2).
Alignment Compression: Alignment coordinates are written to a Binary Alignment Map () file, the compressed binary equivalent of a Sequence Alignment/Map () file.
Read Assignment and Quantification: Dedicated summarization tools (featureCounts or HTSeq) map reads in files against genomic features, generating a matrix of integer read counts (gene identifiers versus experimental conditions/replicates).
Statistical Testing via DESeq2:
Uses negative binomial generalized linear models to analyze the read count matrix.
Evaluates pair-wise sample groups to calculate normalized fold changes (, indicating up- or down-regulation) and Benjamini-Hochberg false discovery rate-adjusted p-values () to establish statistical significance for Differential Gene Expression ().
