Artificial Intelligence
Outcomes
Insights
Patterns found that advise business decisions
Reveal the unknown
E.g.: Frequently bought together
Utility
Can be use repetitively to solve similar tasks, but may not provide insight to solutions
Faster and better solutions to promblems
Data
Structured Data
If the cells are numbers/bools, they can be inputed directly to the machine learning models
If the cells are text, they often need encoding
One hot encoding: Often used for categories that do not have a natural order
Ordinal encoding: Often for categories that have a natural order
Unstructured Data
Tokenization: Seperate the text into individual words
Stemming: Get the root of the word, it helps identify and group similar words
Text data
Term Frequency- Represents in a document the frequency of a word’s appearance

TF-Inverse Document Frequency- penalizes the words that are universal to the documents and doesn’t provide a unique quality to the documents
Trained Embeddings- Deep learning that represents the meaning of words
Clustering
Group similar objects into groups, objects in different groups are less similar to objects in the same group
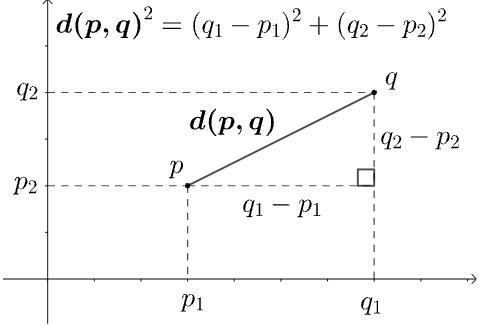
Computers use distance, they use different distances to measure different objects
K-Means
k- predefined as in input
Squared Euclidean Distance
Classification
Pre-defined classes, requires labeled training data (supervised learning)
More often adopted for utility
Decision Tree
Leaves represent class labels
Branches represent conjunctions of features that lead to those class labels
Can provide insights on the decision process