DNA Sequence Alignment
Fundamentals of Sequence Alignment
Definition: Sequence alignment is the method of arranging biological sequences (DNA, RNA, or protein) to identify regions of similarity.
Biological Significance: Similarity identified through sequence alignment can indicate structural, functional, or evolutionary relationships (homology) between sequences.
Mechanism: Alignment algorithms insert gaps () between residues so that identical or characteristically similar nucleotides/amino acids align vertically in columns.
Applications in Genome Sequencing
Genome Reconstruction:
DNA sequencing technologies produce short DNA fragments known as sequence reads.
Alignment algorithms identify where each short read belongs relative to a reference sequence or to other reads.
Overlapping aligned reads enable the assembly and reconstruction of the original complete DNA sequence.
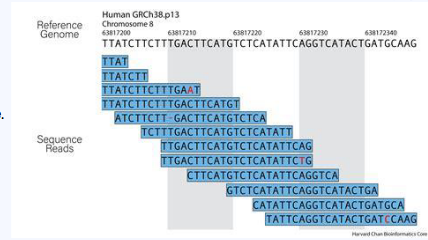
Identification of Genetic Variations:
Comparing aligned sequence reads against a established reference genome reveals structural and point differences, including:
Single Nucleotide Polymorphisms (SNPs): Single base-pair substitutions.
Insertions and Deletions (Indels): Small additions or losses of nucleotide bases.
Structural Variants: Larger genomic rearrangements, duplications, or inversions.
Pairwise Sequence Alignment Strategies
Global Alignment:
Objective: Attempts to align every residue across the full length of both sequences.
Applicability: Optimal for sequences that are of similar length and share high overall similarity.
Core Algorithm: Needleman-Wunsch algorithm.

Local Alignment:
Objective: Identifies discrete, highly conserved regions of similarity (such as functional domains or structural motifs) within sequences, ignoring divergent regions.
Applicability: Optimal for comparing dissimilar sequences, sequences of varying lengths, or searching for conserved domains.
Core Algorithm: Smith-Waterman algorithm.
Representative Tool: EMBOSS Water (
https://www.ebi.ac.uk/Tools/psa/emboss_water/).EMBOSS Water Example Execution (Escherichia vs Mycobacterium):
Scoring Matrix: EDNAFULL
Gap Penalty:
Extend Penalty:
Alignment Length:
Identity Score:
Similarity Score:
Gaps:
Alignment Score:

Pairwise Sequence Alignment Algorithms & Approaches
Dot-Matrix Method:
A two-dimensional graphical matrix where sequence 1 is mapped along the top row (x-axis) and sequence 2 along the left column (y-axis).
Dots are plotted in matrix cells where the characters at corresponding positions match.
Interpretation:
A continuous diagonal line indicates regions of close relation or identical sequence stretch.
Breaks, offsets, or interruptions in the diagonal line denote sequence insertions, deletions, or mutations.

Dynamic Programming:
Computes exact optimal matching by assigning quantitative numerical scores to alignments.
Scoring Parameters:
Match Score: Positive value (e.g., )
Mismatch Score: Negative value (e.g., )
Gap Penalty: Negative value (e.g., )
Worked Example Calculation:
Sequence 1:
A T G C TSequence 2:
A T A C TColumn evaluations:
Pos 1 (A-A): Match ()
Pos 2 (T-T): Match ()
Pos 3 (G-A): Mismatch ()
Pos 4 (C-C): Match ()
Pos 5 (T-T): Match ()
Mechanism: Matrix cells are filled sequentially, storing the highest possible score at each node. The highest-scoring path is traced backwards from the end to extract the globally optimal alignment.
Word (Heuristic/K-mer) Methods:
Significantly more computationally efficient than exhaustive dynamic programming; designed for searching massive sequence databases at high speeds (at the expense of guaranteed mathematically optimal alignments).
Function by identifying short, exact matching words (k-mers).
Used in primary database search engines such as BLAST (Basic Local Alignment Search Tool).
Worked Euclidean Distance Calculation Example:
Query sequence
Query sequence
Word size
Words in ():
ATG,TGT,GTG,TGT,GTGWords in ():
CAT,ATG,TGT,GTGUnion set
Word count vector for ():
Word count vector for ():
Euclidean distance formula:

Evaluation Metrics for Sequence Alignment (BLAST)
Raw Score (): Calculated by summing matches (), mismatches (), and gap penalties ().
Bit Score: Derived by normalizing the raw alignment score () against database size and matrix scoring parameters, allowing standardized comparisons between different searches:
: Weak similarity
: Moderate similarity
: Strong similarity
: Very strong similarity; high confidence of homologous sequences
Expect Value (): Statistical estimate representing the number of distinct alignments with a given score (or higher) expected to occur purely by chance when searching a database of a specific size:
: Approximately matches expected by chance
: Approximately match expected by chance
: chance match per database searches
: Highly significant match
: Extremely significant match
: Essentially zero probability of chance occurrence (identical or near-identical sequence match)
BLAST Score Parameter Worked Example:
Raw Score:
Bit Score:
Expect Value:
Identities:
Gaps:
Match Reward:
Mismatch Penalty:
Gap Penalty Calculation:

Multiple Sequence Alignment (MSA)
Definition: Alignment of three or more biological sequences () simultaneously to identify conserved regions across entire gene or protein families.
Progressive Alignment Methods:
Process: Aligns the most similar pair of sequences first, constructs a guide tree based on pairwise similarity scores, and progressively aligns additional, more distant sequences to the growing alignment.
Primary Tool: Clustal Omega.
Trade-off: Fast and computationally tractable for high sequence counts, but errors made in early pairwise alignment stages cannot be corrected downstream.
Iterative Alignment Methods:
Process: Generates an initial global multiple sequence alignment (typically using progressive methods), then repeatedly recalculates and realigns sub-sets of sequences to continuously refine the overall alignment score.
Primary Tool: MUSCLE (Multiple Sequence Comparison by Log-Expectation).
Trade-off: Higher accuracy than progressive methods because early errors can be corrected during iterative realignment cycles.
Motif Finding:
Process: Performs global multiple sequence alignment followed by isolation and extraction of short, highly conserved functional patterns across sequences.
Performance Comparison of Sequence Alignment Methods
Method | Main Goal | Accuracy | Computational Cost |
|---|---|---|---|
Dynamic Programming | Optimal alignment | Highest | Very High |
Progressive Methods | Fast MSA | Moderate | Low |
Iterative Methods | Refined MSA | High | Moderate |
Motif Finding | Identify conserved functional patterns | High for motifs | Moderate |
Sequence Alignment Visualization Software
MView: Generates formatted HTML displays of sequence alignments. Displays specific metrics including:
cov(Coverage): Percentage of the target/reference sequence length covered by the aligned sequence.pid(Percent Identity): Percentage of identical aligned residues relative to the reference sequence.

WebLogo: Generates graphical representations (logos) of sequence conservation where character height corresponds to information content at each specific nucleotide or amino acid position (measured in bits).
BoxShade: Creates shaded visual outputs highlighting identical or similar residues for publication and structural analysis.

AliView: High-speed sequence alignment editor optimized for inspecting and managing large alignments.
UGENE: Integrated bioinformatics desktop workspace for visualizing sequences, chromatogram traces, and predicting open reading frames (ORFs).

GeneDoc: Interactive sequence alignment editor supporting conservation-based color-shading and similarity matrix scoring.

Jalview: Interactive cross-platform workbench (
https://www.jalview.org/) for editing, analyzing, and annotating multiple sequence alignments.